Grok API Pricing: Every Model Rate, the 200k Rule, and What One Request Costs
On 5 November 2026, we reviewed xAI's developer pricing page and organized the listed charges into model rates, media rates, tool-call fees, and processing options. We also calculated the cost of one sample text exchange using 270 input tokens and 670 output tokens. The token counts came from our separate DeepSeek test, which lets readers compare the arithmetic on the same example. These calculations are estimates based on published rates, not charges from an actual Grok API invoice.
At the rates listed on that date, grok-4.7 cost $2 per million input tokens and $6 per million output tokens; cached input was $0.50 per million. When a request reaches the 200,000-token prompt threshold, xAI says the higher rate applies to all tokens in that request. The listed grok-4.3 rates were lower ($1.25 input and $2.50 output per million) and its context window was 1 million tokens. The page also listed per-image, per-second video, voice, and tool-call charges. Below, we calculate a sample request and explain the extra charges that can change the total.
The text model rate table
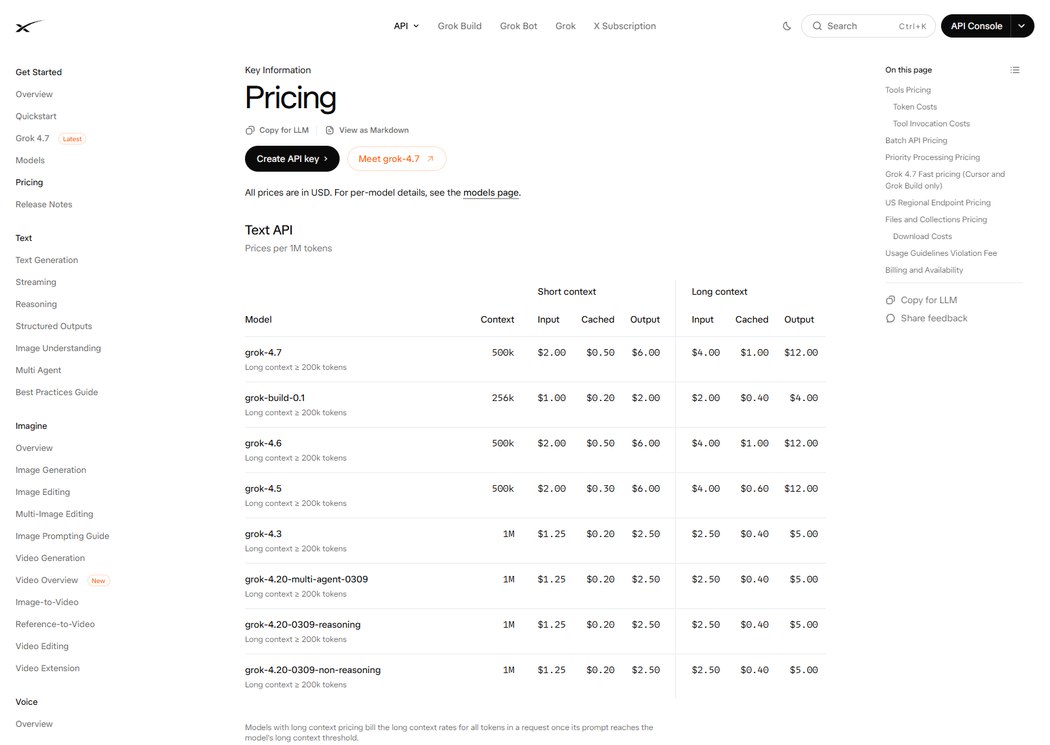
The table below transcribes the text-model rates shown in xAI's developer pricing documentation on 5 November 2026. Rates are in US dollars per million tokens. Rows marked with the 200k threshold use the higher long-context rate when the request prompt reaches that threshold.
| Model | Context | Input / 1M | Cached input / 1M | Output / 1M |
|---|---|---|---|---|
| grok-4.7 (<200k prompt) | 500k | $2.00 | $0.50 | $6.00 |
| grok-4.7 (≥200k prompt) | 500k | $4.00 | $1.00 | $12.00 |
| grok-4.6 (<200k prompt) | 500k | $2.00 | $0.50 | $6.00 |
| grok-4.6 (≥200k prompt) | 500k | $4.00 | $1.00 | $12.00 |
| grok-4.5 (<200k prompt) | 500k | $2.00 | $0.30 | $6.00 |
| grok-4.5 (≥200k prompt) | 500k | $4.00 | $0.60 | $12.00 |
| grok-4.3 (<200k prompt) | 1M | $1.25 | $0.20 | $2.50 |
| grok-4.3 (≥200k prompt) | 1M | $2.50 | $0.40 | $5.00 |
| grok-4.20-0309 (reasoning / non-reasoning / multi-agent) | 1M | $1.25 | $0.20 | $2.50 |
| grok-4.20-0309 variants (≥200k prompt) | 1M | $2.50 | $0.40 | $5.00 |
| grok-build-0.1 | 256k | $1.00 | $0.20 | $2.00 |
The models page listed May 2026 as grok-4.7's knowledge-cutoff date. It also said the model does not know about events or data beyond its training information unless server-side search tools are enabled. Those tools have separate charges, listed in the tool-pricing section below.
The 200k rule: one long prompt doubles every token in the request
The pricing page’s footnote explains how the long-context charge works:
“Models listed with two rows use long context pricing: requests whose prompt reaches the listed token threshold are billed at the higher rate for all tokens in the request.”
The important detail is that the higher rate applies to every token in a qualifying request, not only to tokens above 200,000. For example, a request with a 250,000-token prompt is not priced with the first 200,000 tokens at the lower rate and the remainder at the higher rate. Under the listed grok-4.7 rates, the higher tier is $4 per million input tokens and $12 per million output tokens. If your prompt is close to the threshold, reducing its size may lower the cost substantially. Check the current documentation before implementing a cost estimate, because thresholds and rates can change.
Images, video, and voice
Media generation is billed per output, not per token:
| Model | Price |
|---|---|
| grok-imagine-image-2.0 | $0.04 / image |
| grok-imagine-image | $0.02 / image |
| grok-imagine-video-1.5-lite | $0.020 / second |
| grok-imagine-video | $0.050 / second |
| grok-imagine-video-1.5 | $0.080 / second |
| Speech to Speech (grok-voice-3.0) | $0.08 / minute ($4.80 / hour) + $0.004 / text input |
| Speech to Text | $0.10 / hour (REST), $0.20 / hour (streaming) |
| Text to Speech | $15.00 / 1M characters |
The documentation marks grok-voice-2.0 Speech to Speech as deprecated and lists grok-voice-3.0 at the same $0.08-per-minute rate. At $0.08 per second, a 15-second generation on the top video model in this table would cost $1.20 (15 × $0.08). This is an API calculation; it should not be treated as equivalent to a consumer subscription's video allowance.
Tool calls have their own price list
An agent request can generate both model-token charges and separate server-side tool charges. The token total can include reasoning tokens where the documentation identifies them as billable. The table below lists the tool-call rates shown on the pricing page.
| Tool | Price | How it counts |
|---|---|---|
Web Search (web_search) | $5 / 1k calls | Includes browsing pages |
X Search (x_search) | $5 / 1k posts; $10 / 1k profiles | Per item fetched, including parent and quoted posts |
| Code Execution | $5 / 1k calls | Sandboxed Python |
| Collections Search (RAG) | $2.50 / 1k calls | Queries your uploaded document collections |
File Attachments (attachment_search) | $5 / 1k calls | Searches files attached to messages |
| Image/video understanding | Token-based | No call fee; image tokens for processing |
| Remote MCP tools | Token-based | No call fee; you pay tokens |
For X Search, billing is based on the posts and profiles returned, not simply on the number of times the search button is pressed. The documentation says parent and quoted posts are included in the count, so retrieving a thread can create several billable items.
Batch, priority, and the US endpoint: three multipliers
- Batch API: −20% on grok-4.7, 4.6, 4.5, 4.3, and the grok-4.20-0309 variants, for all token types. Responses return within 24 hours and batch requests do not count toward rate limits. Image and video generation work in Batch but get no discount.
- Priority Processing: 2x on all token types for higher scheduling priority. The docs state prompt-caching discounts apply before the multiplier, and you are only billed the priority rate when the response confirms
"service_tier": "priority". Not available for image, video, or Batch requests. - US regional endpoint: 1.1x. Requests to
https://us.api.x.ai/v1run inference in the United States at a 10% premium — $2.20 / $0.55 / $6.60 per million on grok-4.7 below 200k — and only grok-4.7 and grok-4.6 are available there. The global endpoint ishttps://api.x.ai/v1.
One more rate exists but you cannot buy it on the public API: Grok 4.7 Fast, the same model on faster infrastructure, costs 2x standard rates (1.5x for long context) and is available only inside Cursor and Grok Build, billed through those plans. The docs state plainly that it “is not available on the public xAI API, and Grok Build’s free tier does not include it.”
What one request actually costs — next to DeepSeek
For a simple comparison, we used one sample exchange: 270 input tokens, 670 output tokens, no cache hit, and no tool calls. We multiplied those counts by each provider's published rates. The results are estimates for this one example, not typical costs for every prompt.
| Service / model | Input rate | Output rate | Cost of this exchange |
|---|---|---|---|
| Grok grok-4.7 | $2.00 / 1M | $6.00 / 1M | ≈ $0.0046 |
| Grok grok-4.7, Batch | $1.60 / 1M | $4.80 / 1M | ≈ $0.0036 |
| Grok grok-4.3 | $1.25 / 1M | $2.50 / 1M | ≈ $0.0020 |
| Grok grok-build-0.1 | $1.00 / 1M | $2.00 / 1M | ≈ $0.0016 |
| DeepSeek deepseek-flash, peak | $0.30 / 1M | $1.20 / 1M | ≈ $0.0009 |
| DeepSeek deepseek-flash, off-peak | $0.15 / 1M | $0.60 / 1M | ≈ $0.0004 |
| DeepSeek deepseek-v4-pro, peak | $1.32 / 1M | $3.96 / 1M | ≈ $0.0030 |
For this sample exchange, grok-4.7 comes to about $0.0046. That is roughly five times the listed peak-rate cost for DeepSeek flash in our comparison, and about 1.5 times the listed peak-rate cost for DeepSeek v4-pro. Batch pricing and cached input can reduce Grok's cost; DeepSeek's off-peak rate makes the comparison gap larger. With a cache hit on the 270 input tokens, the grok-4.7 example falls to about $0.0042.
These totals are calculated from the published rates and our measured 270/670 token counts. They are not actual invoices. Your cost will vary with prompt length, answer length, cache hits, tool calls, model choice, and any applicable processing multiplier.
Storage, downloads, and the violation fee
Three smaller line items from the same page that can add to a bill:
- File storage is listed at $0.025 per GiB per day; collection storage is $0.10 per GiB per day. At the file-storage rate, keeping 1 GiB for 30 days would cost about $0.75, before any other charges.
- Downloads: $0.20 per GiB for both files and collections, charged on the way out.
- The documentation lists a $0.05-per-request usage-guideline violation fee for violations caught before generation in the Responses API. It also says requests judged to be in violation are still charged for generation. Check the current policy wording before relying on this fee description.
Frequently asked questions
- Is there a free tier for the Grok API?
- The developer pricing page we checked did not list a free token allowance or a free-credit offer. Grok Build has a free tier, but the documentation says it does not include Grok 4.7 Fast. Paid consumer plans from Plus upward include API access, but API usage is billed separately at model rates. We did not create an API key, so we cannot confirm whether a new account might receive credits through a separate promotion.
- What is the Grok API base URL?
- The global endpoint is https://api.x.ai/v1 and it is OpenAI-compatible, so the OpenAI SDK works by changing the base URL and key. The US regional endpoint is https://us.api.x.ai/v1 and bills at 1.1x standard rates with only grok-4.7 and grok-4.6 available.
- How does prompt caching change the bill?
- Cached input tokens bill at a fraction of the input rate — $0.50 instead of $2.00 per million on grok-4.7, $0.20 instead of $1.25 on grok-4.3. Caching discounts are applied before the batch, priority, and regional multipliers, per the docs.
- Does a long prompt double the whole bill?
- Yes. Once a request's prompt reaches the 200k-token threshold, the higher long-context rate applies to all tokens in that request, including output. A request just over the threshold costs about twice what the same request would cost just under it.
- What does grok-4.7 know about current events?
- Its knowledge cutoff is May 2026 per the docs, and there is no access to realtime events unless search tools are enabled. Web Search costs $5 per 1,000 calls and X Search is billed per post and per profile fetched.
Sources and what we could not test
| Claim | Where it came from | Date checked |
|---|---|---|
| Full text-model rate table, 200k long-context rule, media and voice rates | xAI developer pricing documentation | 5 Nov 2026 |
| Tool prices (web/X search, code execution, collections), per-item X Search billing | xAI developer docs, Tools Pricing section | 5 Nov 2026 |
| Batch −20% model list, priority 2x with service_tier confirmation, US endpoint 1.1x, Grok 4.7 Fast restrictions | xAI developer docs, Batch / Priority / Regional sections | 5 Nov 2026 |
| Storage $0.025/$0.10 per GiB/day, downloads $0.20/GiB, violation fee $0.05 | xAI developer docs, Files and Collections / Usage Guidelines | 5 Nov 2026 |
| grok-4.7 May 2026 knowledge cutoff; no realtime events without search tools | xAI models page, Additional Information | 5 Nov 2026 |
| DeepSeek comparison rates and the 270/670 token exchange shape | our own DeepSeek cost test (token counts measured Oct 2026; rates checked 2 Nov 2026) | 2 Nov 2026 |
We did not create an API key or send a paid request. As a result, we have no actual invoice, billing-dashboard record, rate-limit measurement, or latency test to report. The model list may also vary by region or account. Every cost in the worked example is calculated from the published rates; it is not an observed charge.